Project 04
Fine-Tuned Soccer Discourse Classifier
TakeMeter
TakeMeter tests whether a small fine-tuned language model can distinguish three kinds of discourse inside the same soccer community.
- 220
- reviewed comments
- 75.8%
- DistilBERT accuracy
- 81.8%
- zero-shot baseline
Dataset and model
I manually reviewed 220 r/soccer comments labeled as analysis, hot take, or reaction, then created stratified training, validation, and test splits. DistilBERT was fine-tuned on a GPU and compared with a zero-shot Llama baseline on the same test set.
Evaluation
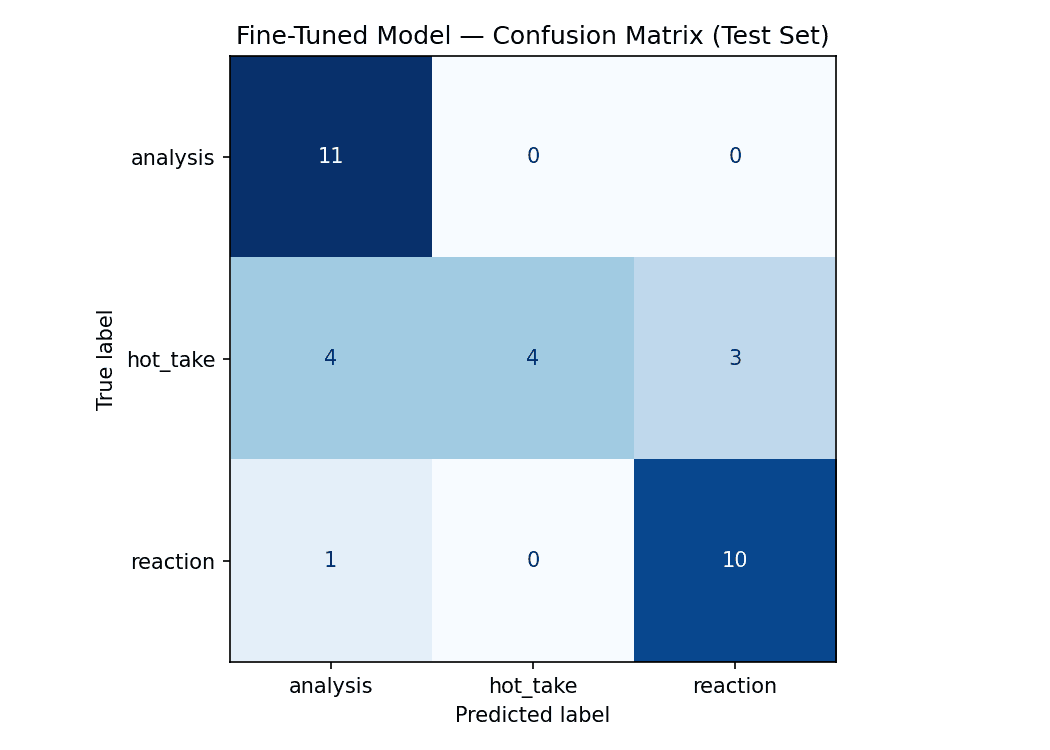
The evaluation measured accuracy, precision, recall, F1, and confusion-matrix errors. DistilBERT reached 75.8% accuracy while the zero-shot baseline reached 81.8%, so fine-tuning did not outperform the baseline.
What the errors revealed
The model separated analysis and reaction more reliably than hot takes. Hot-take examples often borrow tactical language from analysis or emotional language from reactions, while being defined mainly by the absence of meaningful evidence. The confusion matrix makes that weak boundary visible.
Next iteration
The documented next step is not a larger claim—it is better data. More hard-negative hot-take examples would give the model clearer evidence for the class boundary that the first dataset did not capture well enough.